
Belonging & Pupil Voice
Measuring belonging in a multi-academy trust: a practical approach
Measuring belonging in a multi-academy trust only works when every academy uses the same definition, question set and calendar. This practical guide shows how trusts can build a comparable, cohort-level picture of belonging that boards can read and school leaders can act on, looking beneath the average rather than relying on headteacher impressions.
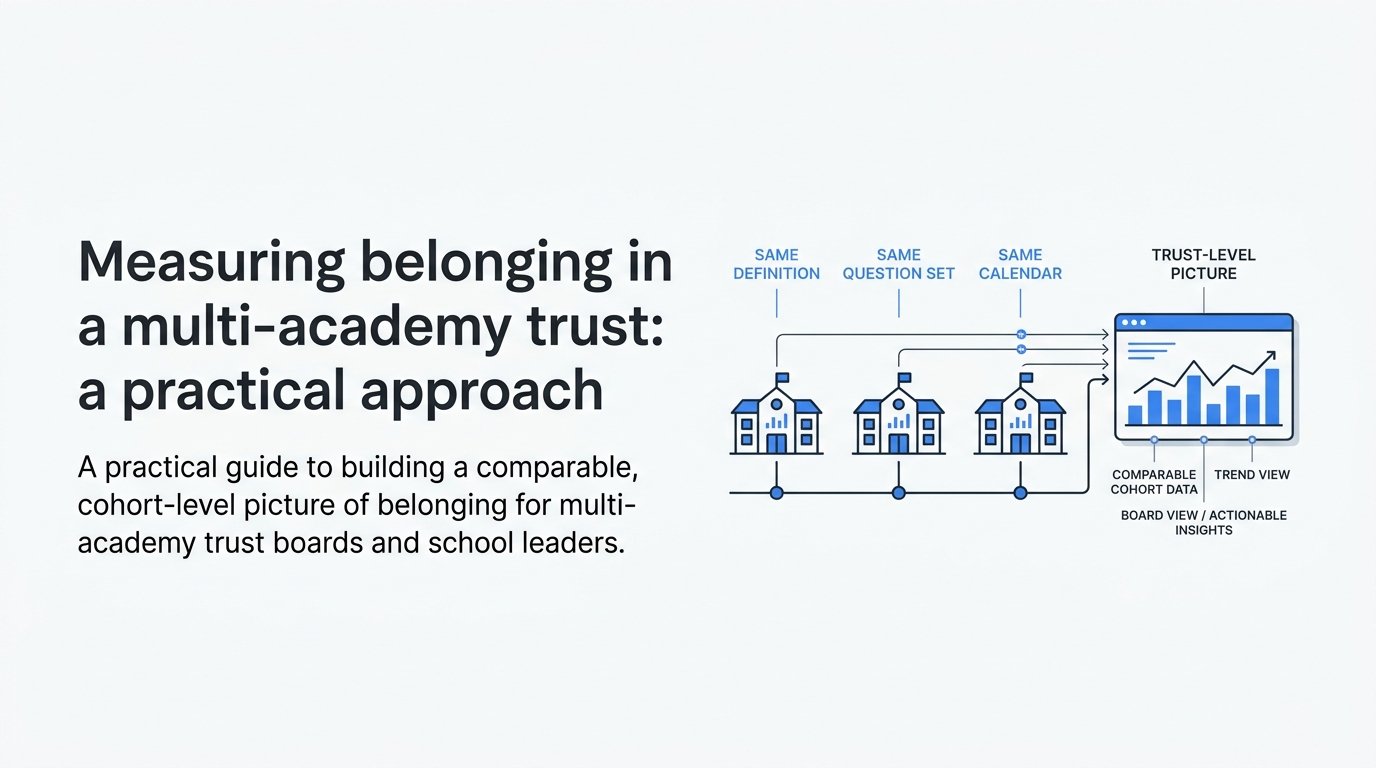
Measuring belonging in a multi-academy trust only works if every academy asks the same questions, in the same way, at the same time. Without that, a board is comparing headteacher impressions, and impressions reflect the person writing them as much as the school. This article sets out how to get a comparable, cohort-level picture of belonging that boards can read and school leaders can act on.
The method is not complicated. It needs a shared definition, a fixed question set, a common calendar, and a habit of looking beneath the average. The hard part is keeping to it across schools with different sizes, phases and intakes.
Why belonging data belongs next to attendance and behaviour
Belonging, in plain terms, is a pupil's sense of being accepted, valued and included, and of being connected to adults and peers at school. Definitions vary across the research literature, so settle on one working definition for the trust and write it down. A one-sentence version, shared with every headteacher, is enough to stop schools measuring different things under the same name.
The link to outcomes is well supported, though the size of the effect varies by study. Allen and colleagues' 2018 meta-analysis in Educational Psychology Review reviewed the school belonging literature and found it associated with academic motivation, engagement and a range of positive school outcomes. The research is largely correlational, so treat belonging as a strong indicator to act on rather than a lever with a guaranteed return. That is a sound basis for a board paper, provided you describe it cautiously.
The case for adding it to board reporting rests on timing. Attendance, suspensions and exclusions are lagging measures. They record a problem once it has taken hold, often after a pupil has already disengaged. Pupil voice shows experience earlier, which is what makes belonging a leading indicator: a signal that something may change in the hard data, not a record of what has already happened.
Most boards already receive MIS, attendance and behaviour reports. Those tell trustees what is happening. Belonging data adds a view of why, and of where to look next. It also comes directly from pupils, staff and families, so it does not pass through the filter of a school's own summary.
What to measure: topics and voices for a trust-wide picture
A single headline score is easy to report and hard to use. If Academy A scores 72 and Academy B scores 68, a trustee learns nothing about what to ask. Break belonging into distinct topics so that a low result points somewhere specific. Useful topics include:
- relationships with staff
- connection with peers
- safety and fairness
- inclusion of different groups
- voice and participation
- enjoyment of learning
Each topic suggests a different response. Weak peer connection in Year 7 leads to questions about transition and tutor groups. Low scores on fairness lead to questions about how behaviour policy is experienced. A headline number cannot do that.
Hearing from staff and families as well as pupils
Pupil voice alone gives half a picture. Staff belonging is closely tied to workload, retention and the consistency of adult relationships that pupils depend on. A staff survey that shows concerns clustered in one phase or one academy tells a trust where turnover risk is building. Parent and carer views add what pupils cannot report, such as how welcome families feel and whether communication reaches them.
Use the same topic structure across all three groups where you can, so that you can read them side by side.
Design choices that protect comparability
The most common mistake is letting each school write its own questions. Local flexibility feels respectful, but it makes comparison impossible. Agree a core set for the whole trust and, if schools want local additions, keep them separate from the core.
A few practical points matter more than they seem:
- Keep the survey to 5 to 10 minutes. Longer surveys lose pupils towards the end, and the later questions suffer.
- Use age-appropriate wording, with a primary version and a secondary version that measure the same topics.
- Make the survey accessible to pupils with English as an additional language, through translation and read-aloud support.
Making results comparable across academies
Comparability comes from three things held constant: identical questions, an identical method, and identical timing. If one academy surveys in the first week of term and another in the week before exams, a difference in scores may reflect the calendar rather than experience. Running the survey termly, in an agreed window, also builds the trend line that a single survey cannot give you.
Agree two further rules before launch. The first is a response-rate expectation. A trust might ask each academy to reach a set proportion of pupils, and treat results below that as indicative only. The second is whether surveys are anonymous or named. Anonymous surveys tend to produce more candid answers. Named surveys let a school follow up with individual pupils and build cohorts from MIS data. Many trusts choose named surveys for pupils, with clear explanation of who sees what, and anonymity for staff. Whatever you choose, apply it consistently and say plainly what pupils and staff can expect.
Consider an illustration. A trust of eight secondary schools compares Year 7 belonging in the autumn term. Two academies score noticeably lower on peer connection than the rest. The trust does not rank the schools. It asks what differs in their transition arrangements: how tutor groups were formed, how much primary liaison took place, and what happened in the first fortnight. The conversation is about practice, and the two headteachers can learn from the schools that scored higher.
Take care with small differences. Before drawing any conclusion, check response rates and cohort sizes. A three-point gap in a year group of 40 with a modest response may be noise. Compare each academy with its own previous results as well as with the trust average. An academy that has risen steadily from a low base is telling a better story than the average suggests, and one that has slipped from a high base deserves a look even if it still sits above the trust mean.
Looking beneath the average: cohort breakdowns
A healthy overall score can hide a gap for particular groups. If most pupils feel they belong, the pupils who do not are a small share of the total, and the average barely moves. The groups worth examining are the ones trusts already track for attainment and attendance: Pupil Premium or disadvantaged pupils, pupils with SEND, EAL, FSM, children in care, and combinations of these. A cohort is simply a defined group of pupils whose results you read together.
Build cohorts from MIS data rather than asking pupils to say which groups they belong to. Self-identification is unreliable, uncomfortable for many pupils, and inconsistent between schools. Where the survey is linked to the MIS, cohorts follow the records the school already holds, and every academy defines them the same way.
Set a minimum group size before anyone looks at results. Reporting on a cohort of three pupils can identify individuals, even in an anonymous survey. Many schools use a floor of around ten, but the right number is a local judgement. Hide or merge any group below it, and tell staff that you have done so.
Here is an illustration. A primary school has strong overall belonging. When the results are split by cohort, Year 5 pupils with SEND report feeling less heard than their classmates. The SENCO and class teachers review how pupils with SEND take part in class discussion, how their views feed into support plans, and what pupil voice routines exist. They agree two changes, a named owner for each, and a date to look again at the next survey.
Read a cohort gap as a prompt for questions. It is not a verdict on the teachers or the school. A gap might reflect timetabling, the way a classroom is organised, or something that has never been asked about before. The useful response is curiosity: what are we doing for this group, and what do they say would help?
Turning results into action each term
Data changes nothing until someone owns a response. A repeatable termly cycle keeps that from slipping:
- Measure with the common survey in the agreed window.
- Break results down by topic and cohort.
- Share them with the people who can act, starting with the headteacher and relevant leads.
- Respond with a small number of actions, each with a named owner and a date.
- Check at the next survey whether the scores for that topic or cohort moved.
Closing the loop with pupils and staff matters as much as the analysis. A short "you said, we did" message, shared in assembly, tutor time or a staff briefing, shows that answers lead to something. It also supports response rates next term, because people complete surveys they believe will be read.
The same cycle works for staff voice. Suppose a staff survey shows workload concerns clustered in one phase. The trust identifies a specific driver, for instance the volume of data entry points across the term, and agrees a change to the assessment calendar. The phase leader owns it, and the trust repeats the staff survey the following term to see whether the workload scores moved. If they did not, the next conversation starts from evidence.
Collating all of this by hand across several academies is where many trusts stall. Matching spreadsheets, rebuilding cohorts and formatting reports can take longer than the analysis. Perceptions is built for this stage: it provides common surveys, cohort breakdowns drawn from MIS data and a trust-wide view in one place, with comparison against previous surveys and AI analysis of free-text comments.
For boards and trustees, the most useful reporting is the direction of travel and the actions agreed. A one-page summary showing each topic's trend over several terms, the cohorts being followed and the owner of each action tells trustees more than a table of scores. It also keeps the conversation on improvement and away from ranking.
Common pitfalls when starting trust-wide measurement
Most failures come from a short list of causes, and each is avoidable.
Surveying once and filing the results. A single survey gives a snapshot with no direction. Belonging needs repeat measurement before a trust can say whether anything is improving or slipping.
Overloading the survey is the second risk. Every added question lowers completion and the quality of the later answers. Launching without explaining the purpose has the same effect. Pupils and staff who do not know why they are being asked, or who will see their answers, tend to respond cautiously or not at all. A short explanation from the headteacher, before the window opens, is worth the time.
Treating the data as a league table is the most damaging habit. When schools expect to be ranked, they start managing the result: coaching pupils, choosing the survey week carefully, or quietly narrowing who is invited. Present results as a prompt for questions and support, and have the trust ask what each academy needs rather than where it placed.
Finally, avoid collecting more than you can act on. If every academy leaves each term with fifteen priorities, none of them will happen. Start with two or three per academy, give each an owner, and add more only when those are moving.
One step to take this term
Agree a shared question set and a single survey window across every academy in the trust. Then pick one cohort or year group, Year 7 is a sensible choice, and review its results first, with a named owner responsible for any follow-up. A narrow start produces a first comparable dataset, a worked example for headteachers, and a baseline to measure against next term.
If collating results across academies is likely to slow you down, Learn more about our services.
See how belonging looks across your schools
Perceptions lets you survey students, staff and parents, compare results across schools and cohorts, and track change over time.
Find out about the Belonging Audit


Related articles
Contact our education team
